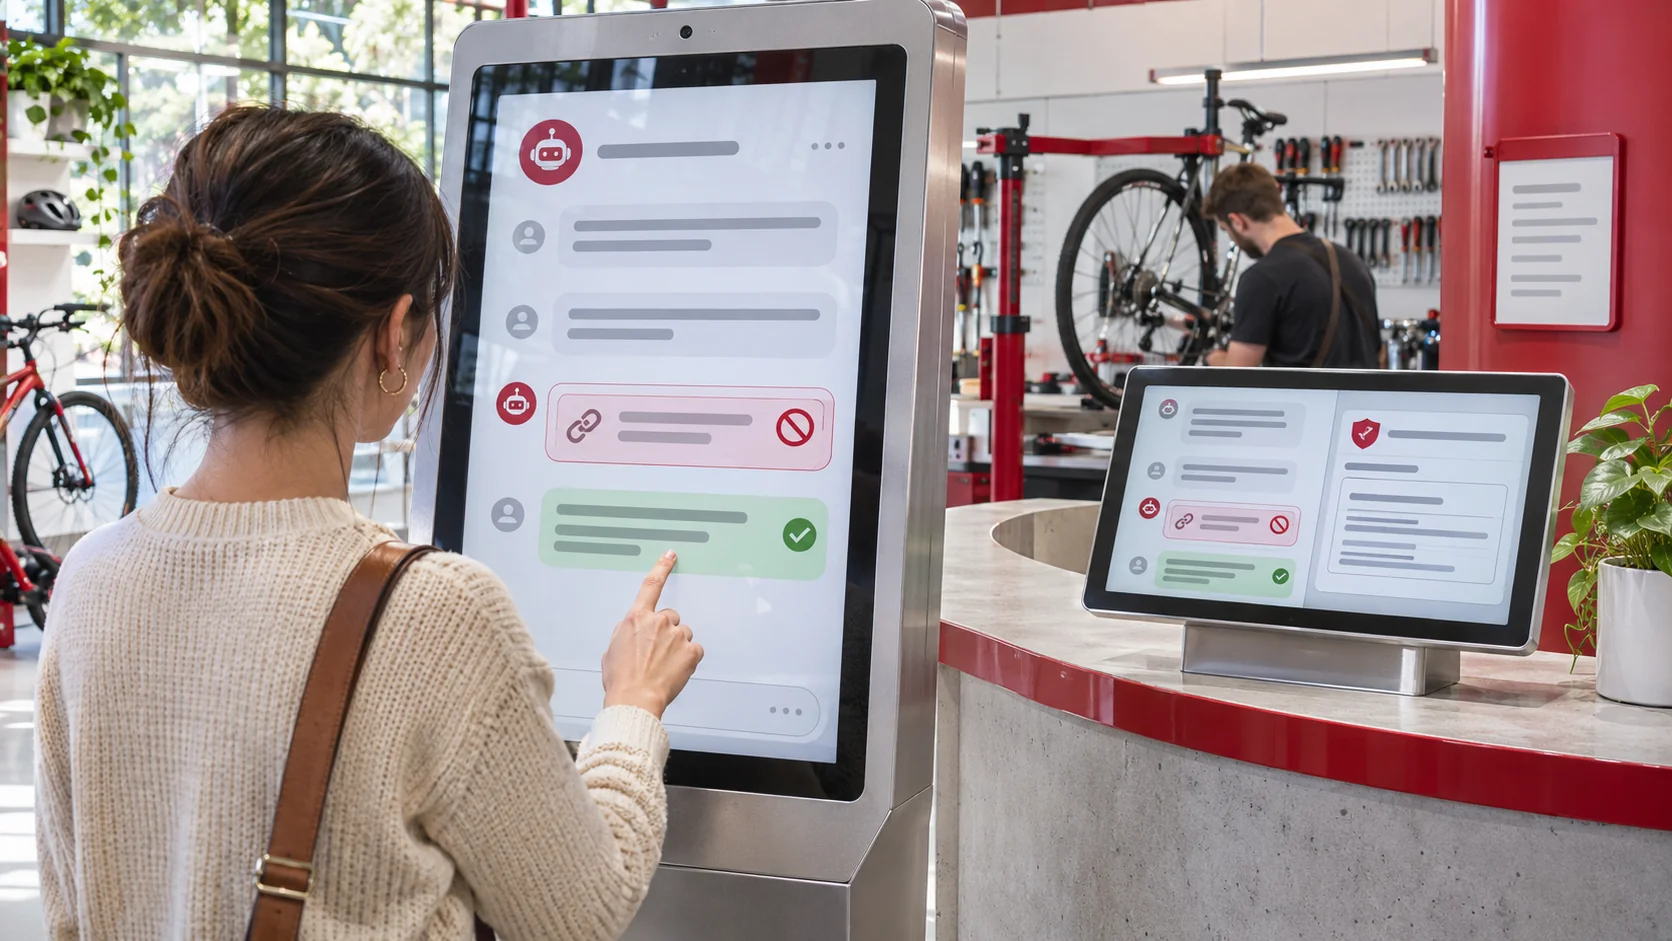
Imagine a customer asking your AI assistant where to update their payment details. The answer reads well and includes a convenient button. But who checked where that button goes? AI output handling is the boundary between generated content and what your customer’s browser is allowed to display or do.
This is a hypothetical example, not a reported Xpansion incident. The business risk is concrete: a plausible answer can carry an unapproved destination or active content. Reviewing the wording alone does not establish that the interface is safe.
The answer is text. Your application can make it active.
A language model produces content in response to its instructions and context. That context may include customer messages, retrieved documents or external pages. It can influence the answer without being an authorised source of application commands.
The critical step comes afterwards. If your application converts generated Markdown into clickable links, inserts generated HTML into a page, or passes generated instructions to another system, it gives that output additional meaning. A harmless-looking sentence and a browser instruction are not the same thing.
OWASP identifies insufficient validation and sanitisation of model responses as improper output handling. In an unsafe integration, generated content can become a route to cross-site scripting: code running in a page rather than text being displayed. Whether that is possible depends on the renderer and surrounding controls, not merely the model brand.
For an Australian business, the consequences could include a customer following a convincing false payment link, an altered support page or exposed information accessible within an affected session. These are conditional risks, not claims that every chatbot can run code or bypass account permissions. A model does not need payment-system access to produce a misleading destination that your interface makes clickable.
AI output handling needs rules outside the prompt
“Only produce safe answers” is a useful instruction, not an enforceable boundary. Ask the application owner what happens when the model produces something unexpected.
- Render text as text. Use safe framework defaults and text-only rendering where rich content is unnecessary. Do not bypass escaping simply to make answers look more polished.
- Constrain rich content. Where formatting is genuinely needed, use a maintained sanitiser with a narrow allowed set. Validate link schemes and destinations separately. A clickable HTTPS address can still lead to the wrong organisation.
- Keep actions separate. Prefer application-created buttons pointing to approved routes over model-created payment or account links. The server must still authenticate the user and authorise each action.
- Validate each destination. A response safe for a chat window is not automatically safe inside an email, database query or system command. Each receiving component needs controls appropriate to its own interpretation.
There is a trade-off: strict rules can remove useful formatting or block legitimate new destinations. Give exceptions a named owner and a controlled release process. Do not solve the inconvenience by trusting all generated HTML.
Ask for evidence from the finished customer journey
Before release, have the technical owner test the actual chat interface, not just sample answers in a model playground. Use a non-production environment and synthetic data to test unexpected markup, unapproved links and malicious instructions embedded in retrieved material.
Record what the customer sees, which requests the browser makes and whether prohibited content is rejected before display. Include both ordinary helpful answers and deliberately awkward inputs. Re-run these checks when the model, Markdown renderer, sanitiser or integration changes. Content Security Policy can provide another defensive layer, but it is not a replacement for safe rendering.
If unsafe output has already reached customers, pause the affected rich-content path, preserve relevant records and identify the actual destinations or actions involved. Assess any personal-information exposure separately. For entities covered by the Australian Privacy Principles, APP 11 requires reasonable steps to protect personal information; a chatbot defect alone does not establish a notifiable breach.
How Xpansion can support your next step
Make output validation part of your AI and intelligent automation requirements, with clear ownership between the business and its application provider. Start by asking for one demonstrated boundary: an unsafe generated answer must not become a trusted customer action.
References
- OWASP: LLM05:2025 Improper Output Handling.
- OWASP: Cross Site Scripting Prevention Cheat Sheet.
- OAIC: APP 11, security of personal information.
Practical evergreen guidance based on directly checked sources, not a new incident advisory. OWASP is a technical security community, not an Australian regulator. General technology information, not legal advice.