Before a team uploads customer notes for an AI summary, somebody removes the names and email addresses. The file looks anonymous. But AI data de-identification requires a harder question: could the remaining details still point to a person?
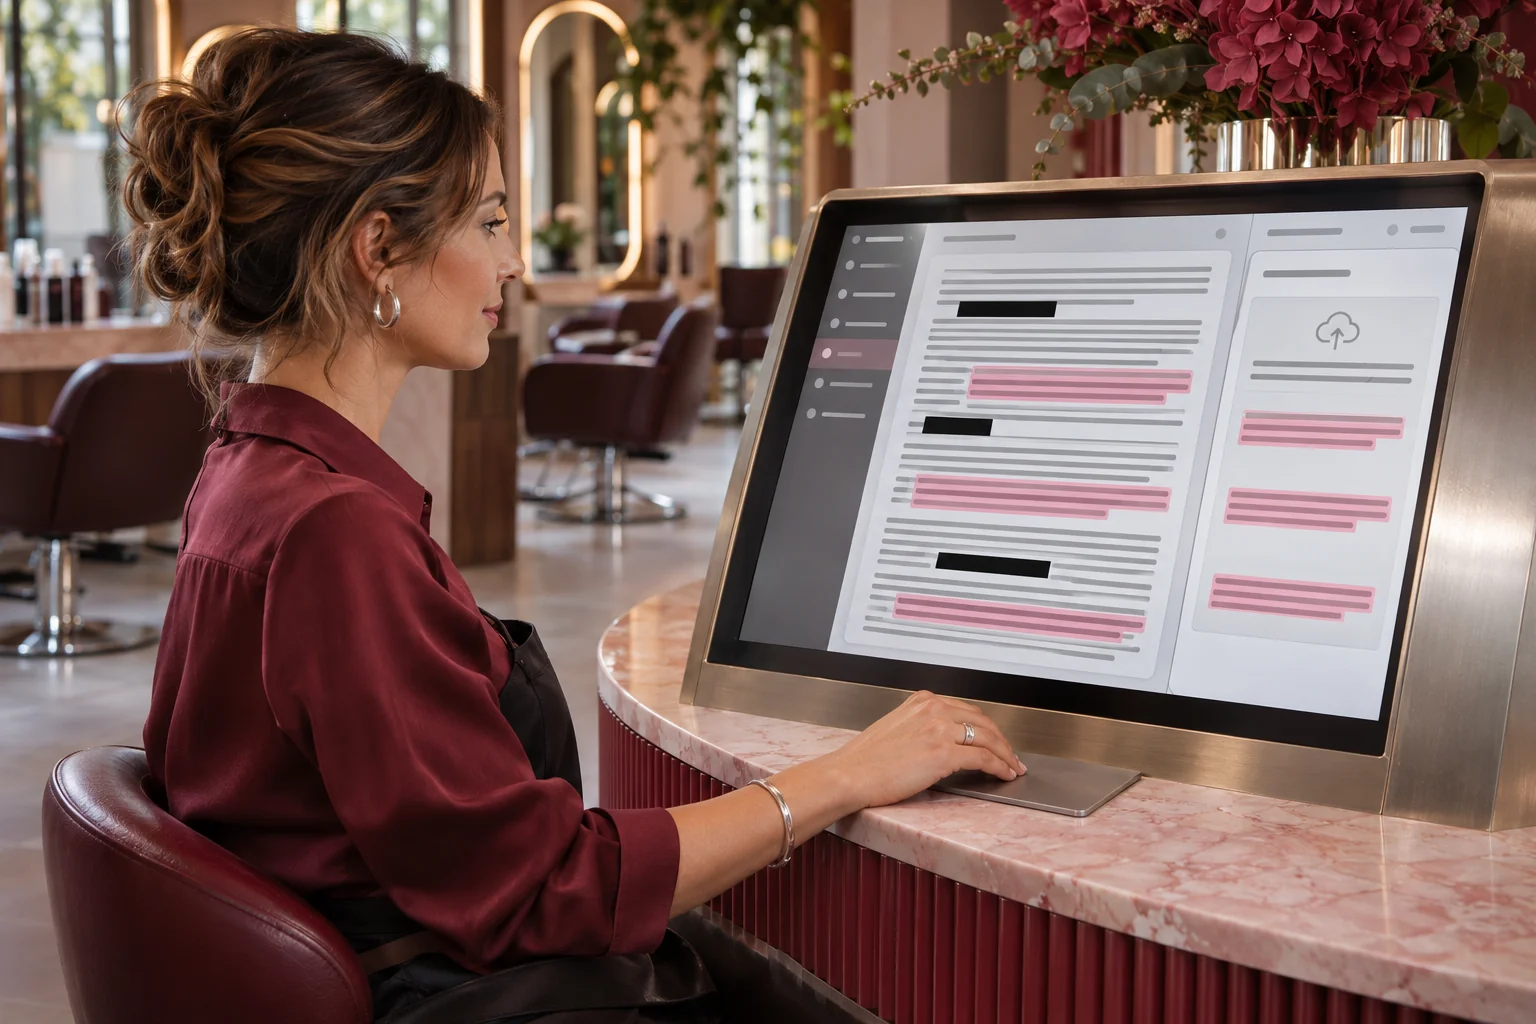
Consider a hypothetical salon preparing a complaint summary. The customer’s name is gone, but the notes retain an unusual treatment, an exact appointment date and a distinctive public review. Together, those details could make the customer reasonably identifiable to someone with matching information. Removing one field has not necessarily removed the privacy risk.
Why removing names is not the same as de-identification
A direct identifier names a person. Context can identify them indirectly. An uncommon occupation, precise location, medical detail or unique sequence of events may become identifying when combined with other available information. This is a linkage problem, not simply a search-and-replace task.
The OAIC explains that effective de-identification considers both the information and the environment into which it is released. Removing direct identifiers alone may be insufficient. The risk of re-identification must be very low in that environment. A file suitable for a tightly controlled internal analysis is not automatically suitable for a different provider or a wider audience.
An AI tool does not need to correctly name the customer for a problem to arise: staff may already have sent reasonably identifiable information outside the approved workflow. Nor should a convincing AI guess be treated as proof of identity. Generative systems can produce incorrect information about people, creating a separate risk if staff copy it into customer records.
AI data de-identification needs a release decision
The business decision is not whether a document contains black boxes. It is whether the remaining data, the intended recipient and the proposed task are appropriate together. A prompt saying “do not identify anyone” does not remove identifying details from the input.
- The information owner: Decide what the task actually needs. A service-improvement summary may need complaint themes, not individual appointment histories. Remove unnecessary records and generalise exact dates or locations where that preserves useful meaning.
- The technical owner: Check the actual exported content before upload. A visible covering rectangle is not evidence that underlying text has been removed. Test search and copy operations on the release copy, and inspect associated files or fields rather than relying on a screenshot.
- The privacy owner: Assess remaining combinations and who could link them. Record why the release is acceptable, which environment was assessed and what changes would require reassessment. Seek specialist advice for detailed or sensitive datasets.
Check the AI destination, not just the file
Verify the product, account type and contractual settings actually in use. Establish who can access prompts and outputs, retention and deletion arrangements, and whether submitted material can be used for training. A supplier’s “not used for training” setting does not, by itself, prove that information is de-identified or that its disclosure is authorised.
For organisations covered by the Privacy Act, the OAIC’s commercial-AI guidance explains that privacy obligations apply to personal information in inputs and outputs. Its best-practice recommendation is not to enter personal information, particularly sensitive information, into publicly available generative AI tools. Coverage and applicable obligations should be checked for the particular business; not every Australian small business has identical obligations.
Keep useful analysis without exposing the customer
Start with fictional test cases or genuinely aggregated themes when individual records are unnecessary. If real cases are essential, use an approved environment and a documented assessment rather than treating redaction as automatic permission. More generalisation can reduce analytical detail, so record that trade-off instead of quietly restoring identifying fields.
Keep a release record: the exact file version, purpose, recipient, checks performed and accountable owner. Reassess when a tool gains connected data sources or the audience changes. A successful sample test is useful evidence, not a guarantee against every future linkage.
When planning business AI workflows, include these data boundaries in your AI and intelligent automation requirements. The useful question is not “Did we delete the name?” It is “What could this remaining information reveal, to whom?”